Understanding Machine Learning Optimizers: SGD vs. Adam
When training modern artificial intelligence models, the choice of optimization algorithm remains a critical decision for developers and machine learning engineers. A technical review published by Unite.ai explores the fundamental mechanics of how machine learning optimizers function, focusing specifically on a comparative analysis between Stochastic Gradient Descent (SGD) and the Adaptive Moment Estimation (Adam) optimizer.
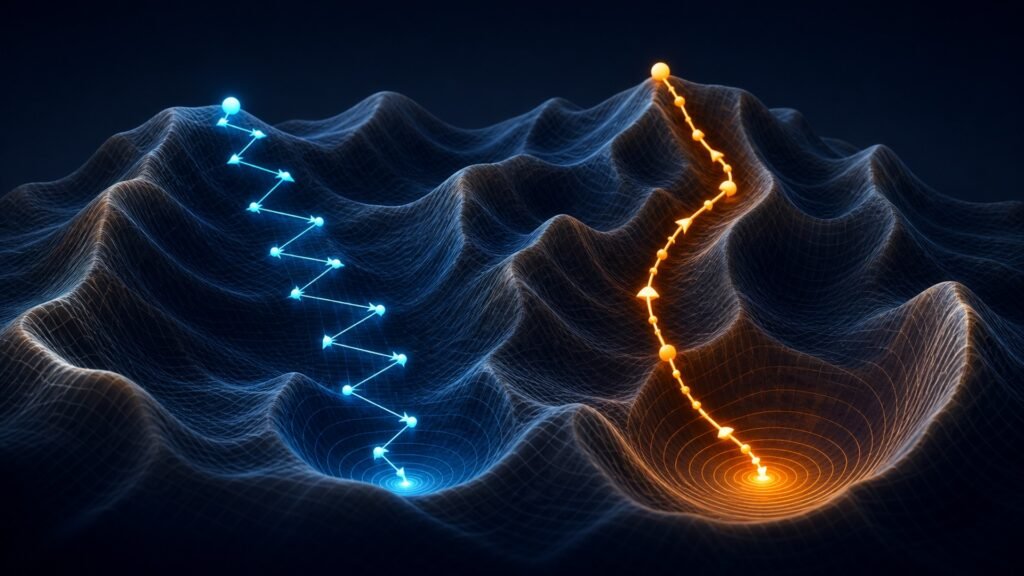
According to the Unite.ai report, machine learning optimizers are responsible for updating network weights based on computed gradients during the training process, effectively steering the model toward minimum loss. While basic SGD updates parameters sequentially using individual or small batches of data samples, it can sometimes struggle with navigating complex error surfaces, leading to slow convergence or getting trapped in local minima.
On the other hand, the Adam optimizer combines the principles of both Momentum and Root Mean Square Propagation (RMSprop). By maintaining exponential moving averages of both past gradients and squared gradients, Adam dynamically adjusts the learning rate for each individual parameter. This adaptive capability allows developer platforms and deep learning systems to train more efficiently across a wide variety of network architectures and datasets.
As AI applications and neural networks continue to grow in scale and complexity, understanding the underlying mathematical behavior of these optimizers helps machine learning practitioners fine-tune developer workflows, improve training stability, and achieve optimal performance in production environments.
Based on reporting by www.unite.ai.