Medical Data Risks AI Misdiagnoses
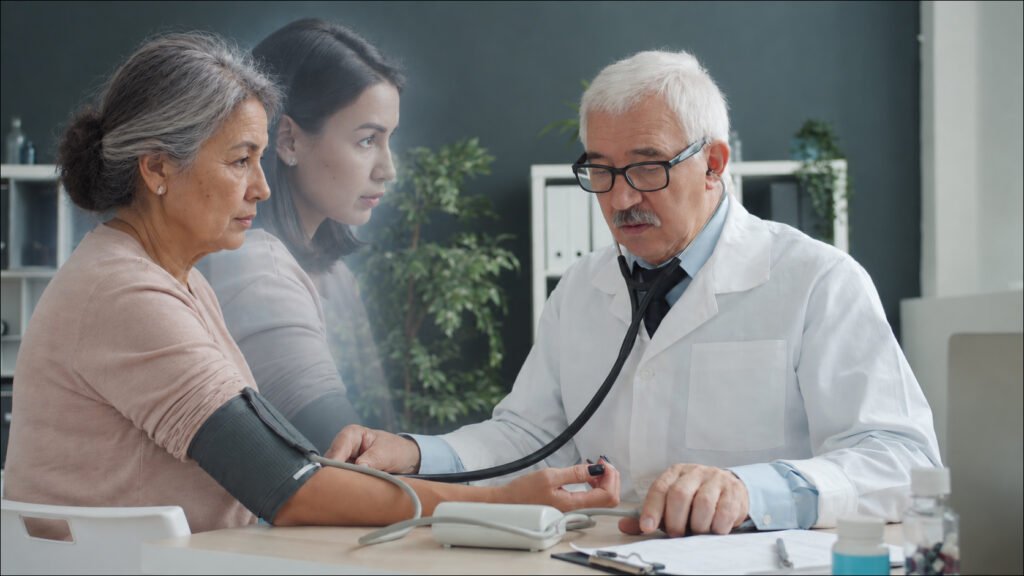
Decades-old anonymized medical data used to train modern artificial intelligence healthcare systems may introduce critical vulnerabilities and lead to clinical misdiagnoses, according to recent analysis published by Unite.ai. As healthcare providers increasingly adopt machine learning models for patient care and diagnostic workflows, the foundational datasets powering these algorithms face scrutiny regarding their age, relevance, and historical collection biases.
According to the Unite.ai report, legacy medical information often lacks the demographic diversity, technological precision, and diagnostic context found in contemporary clinical datasets. When artificial intelligence tools ingest these older, anonymized records, the algorithms can inherit structural blind spots. These limitations potentially impair an agent or diagnostic product’s ability to accurately evaluate modern patients presenting with complex symptoms.
Industry researchers emphasize that medical technology developers must rigorously audit historical training data before deploying clinical artificial intelligence applications. Without careful curation and validation against current clinical standards, legacy datasets risk degrading the reliability of AI-driven tools in hospitals and diagnostic laboratories. Addressing these data integrity challenges remains a priority for software developers aiming to secure regulatory approval and maintain clinical trust in automated medical systems.
Based on reporting by www.unite.ai.