Liquid AI Releases LFM2.5-VL-3B-DSpark
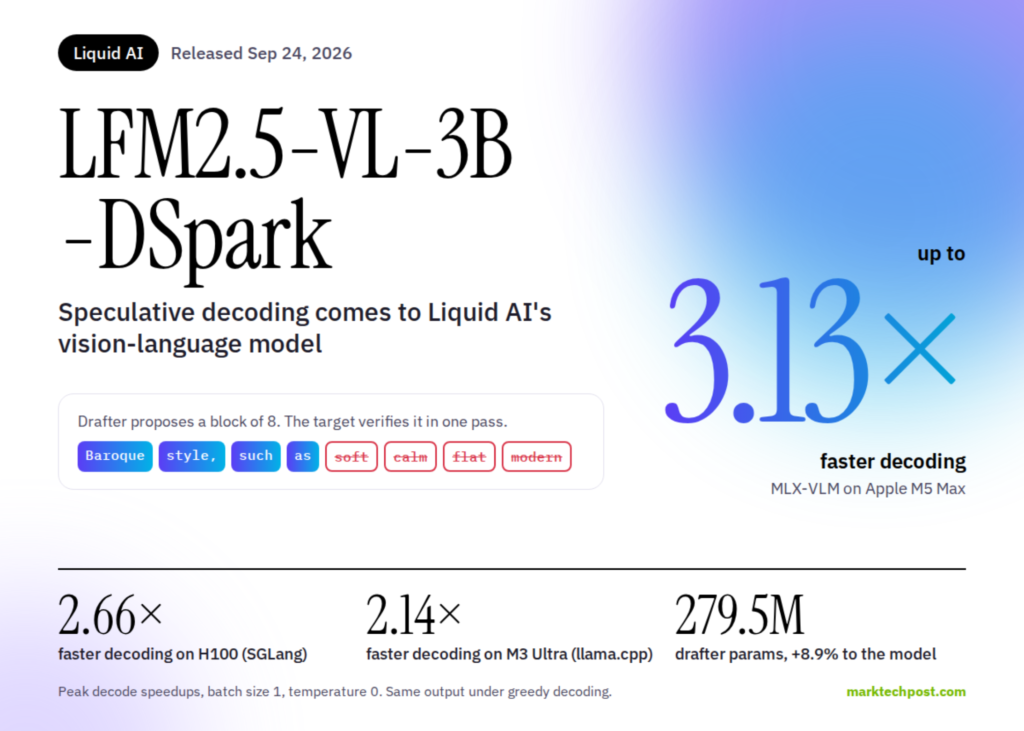
Liquid AI has officially rolled out LFM2.5-VL-3B-DSpark, a new release designed to improve processing performance for vision-language models through speculative decoding techniques. According to MarkTechPost, the newly introduced architecture achieves up to 3.13 times faster decoding speeds compared to standard setups.
The system utilizes specialized speculative decoding strategies tailored for multimodal workflows, allowing developers and enterprise users to handle complex visual and textual data more efficiently. By optimizing inference speed for smaller parameter footprints, the release addresses persistent latency hurdles in deploying real-time vision-language applications.
As competition intensifies across the artificial intelligence sector for faster and more resource-efficient edge models, tools like LFM2.5-VL-3B-DSpark highlight the industry shift toward optimizing inference pipelines. Liquid AI continues to position its architecture lineup toward high-throughput, low-latency deployments across diverse computing environments.
Based on reporting by www.marktechpost.com.